
I gave my monitoring tool an MCP server, so Claude can run my on-call
By Chris Collareta · Published · Updated · 7 min read
Faultline is a monitoring and incident tool with a built-in MCP server, so an AI agent like Claude can check service health, diagnose an incident, and, only after you approve it, run the runbook that fixes it. I built it because no monitor I tried could do that, or could watch the jobs that fail without a URL.
Why build another monitoring tool?
Because the failures that hurt most never touch a public endpoint. Every monitoring tool I tried watched the same thing: a public HTTP endpoint returning 200. That covers your homepage. It does not cover the nightly backup that silently stopped three weeks ago, the queue worker that wedged at 2am, or the ECS task crash-looping since the last deploy. Those turn into a support ticket before you ever see a red light.
The second problem was the paging. Most tools fire on the first failed check, so a 200ms network blip wakes someone up. And when something genuinely breaks, there is no runbook, no context, no escalation path, just a Slack panic and someone grepping logs. So I wanted one system that owns the whole loop: detection, incident, escalation, runbook, resolution, post-mortem. Without a $500/month stack of two or three tools wired together.
That is Faultline. Here is what it actually does today, and the one piece I think nobody else has yet.
How does an AI agent operate Faultline?
Through an MCP server. Faultline ships one, speaking the Model Context Protocol that Anthropic published as an open standard for connecting AI assistants to the systems they work with. If you use Claude Code, Claude Desktop, or any MCP-compatible agent, you can point it at your infrastructure and it can check service health, inspect incidents, see who is on call, and, with your approval, run a runbook that restarts or scales a service. The same agent loop runs three ways over one shared toolset:
- MCP: remote Streamable HTTP server (
mcp.fltln.io), ten tools, API-key auth. - CLI:
faultline ask "why is checkout-api degraded?" - Slack:
@Faultline what is down?
Here is the demo that sold me on building it. An incident opens and you ask Claude what is wrong. It reads the timeline, the recent checks, the sibling services, and the service's runbooks. Then it comes back with: this looks like the connection-pool exhaustion from last Tuesday, and the restart-api-pool runbook fixed it then.
It cites the past incident. You say run it. It executes, waits 120 seconds, reads the service status back, and confirms recovery, or escalates to a human if the service is still down.
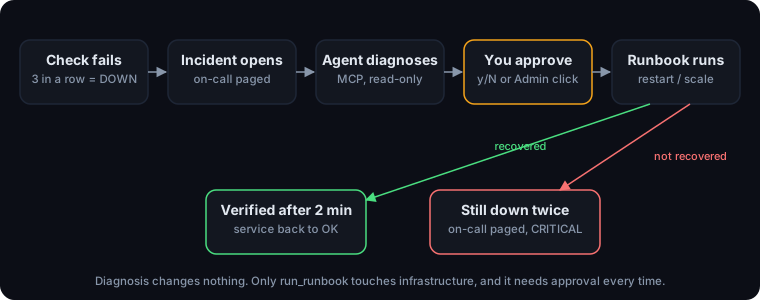
The safety model matters and I want to be precise about it. Analysis and execution are separate calls. Diagnosis recommends but changes nothing. Running a runbook is the only tool that touches infrastructure, and it is gated behind explicit approval every time: a y/N in the CLI, a separate admin action in the dashboard. If the model hallucinates a runbook ID, the API validates it against the incident service's real runbooks server-side and downgrades an unknown ID to "escalate." A cross-tenant or invented runbook cannot be surfaced, let alone run.
What else does Faultline do?
It runs the whole incident loop: seven monitor types, gradual failure states, learned latency baselines, automatic escalation and runbooks, and AI write-ups.
Seven monitor types, not one. HTTP, Docker, ECS, TCP, SSL, DNS, and heartbeats. A heartbeat monitor inverts the model: your job pings Faultline, and if the ping stops arriving past its interval plus grace, the job is down and the full incident pipeline fires. One line at the end of a cron job:
0 3 * * * /usr/local/bin/backup.sh && curl -fsS https://api.fltln.io/hb/hb_YOUR_TOKENThat is how you monitor the things with no URL. Faultline uses the same mechanism to watch its own workers.
Progressive degradation, not binary. A service moves OK to DEGRADED to DOWN on consecutive failure counts, not a single bad check. You define what "broken" means for your service, so you do not get paged for a blip.
Anomaly detection that knows your week. Beyond hard up/down thresholds, a worker learns each service's latency baseline from the same hour-of-week over the trailing four weeks, so a normal Monday-morning traffic ramp is not mistaken for a regression. A sustained, genuine regression opens an incident before it trips a failure threshold; a one-off spike stays advisory.
The loop closes itself. A threshold crossing auto-opens an incident, resolves on-call from the rotation, fans out to email/Slack/PagerDuty/webhook, and offers the matching runbook for approval (or starts it, if you switched that runbook to Auto-run). When a shared dependency takes down ten services at once, alert correlation collapses the storm into one root incident and pages once, not ten times.
Incidents that write themselves up. Every incident can generate an AI summary and, on resolve, a blameless post-mortem. The MTTA and MTTR numbers are computed in code and handed to the model, so the math is exact and only the prose is drafted. Every resolved incident is embedded and becomes precedent, so the next diagnosis can cite the incident that already fixed this.
A design rule I held to: AI is never on the hot path. The check pipeline never waits on a model call, and every prompt is built from fixed-size queries, so cost and latency are constant per call regardless of how much history you have. If you do not set an API key, every AI feature degrades cleanly to a "not configured" notice and nothing else breaks.
How does Faultline compare to UptimeRobot, Datadog, and PagerDuty?
It sits between them: more than a ping checker, much less than a full APM, and it does its own detection, unlike a pure pager. I will be honest about the landscape. UptimeRobot, Pingdom, and Better Uptime have great public HTTP checks but no incident loop and no internal-process visibility. Datadog and New Relic are full observability at $500 to $2,000 a month, overkill for a five-person team; if you need distributed tracing, Faultline is not that, and I am not pretending it is. PagerDuty and Opsgenie do excellent escalation but zero monitoring, so you bring your own detection layer and pay for two products.
Google's SRE book sets the bar for paging plainly: every page should be actionable, which is hard when detection and paging live in different tools. Better Stack is the closest overlap and genuinely good, but weaker on Docker/ECS and with no agent-operable API.
Faultline is for the 2-to-25-engineer SaaS team that needs more than a ping and less than a full APM. Free tier is $0 (5 monitors). Pro is $49/month. The AI copilot, anomaly detection, and the MCP server are in every tier, including free, not a top-shelf add-on.
What does Faultline not do?
It is not an APM. No distributed tracing, no log aggregation. Multi-region quorum probes, a service dependency graph, SLO/error-budget tracking, and monitors-as-code are on the roadmap, not shipped. But the loop is real today, and your AI agent can drive it. That is the part I could not find anywhere else, so I built it.